[ The platform ]
Reliability as a servicefor GPU clusters.
The operations reliability platform behind every cluster we build. SLA-backed, with our engineers standing behind it.
[ What you get ]
Every fault contained,checked against the design.
Factryze watches every node from acceptance onward.
Fleet intelligenceFactryze platform
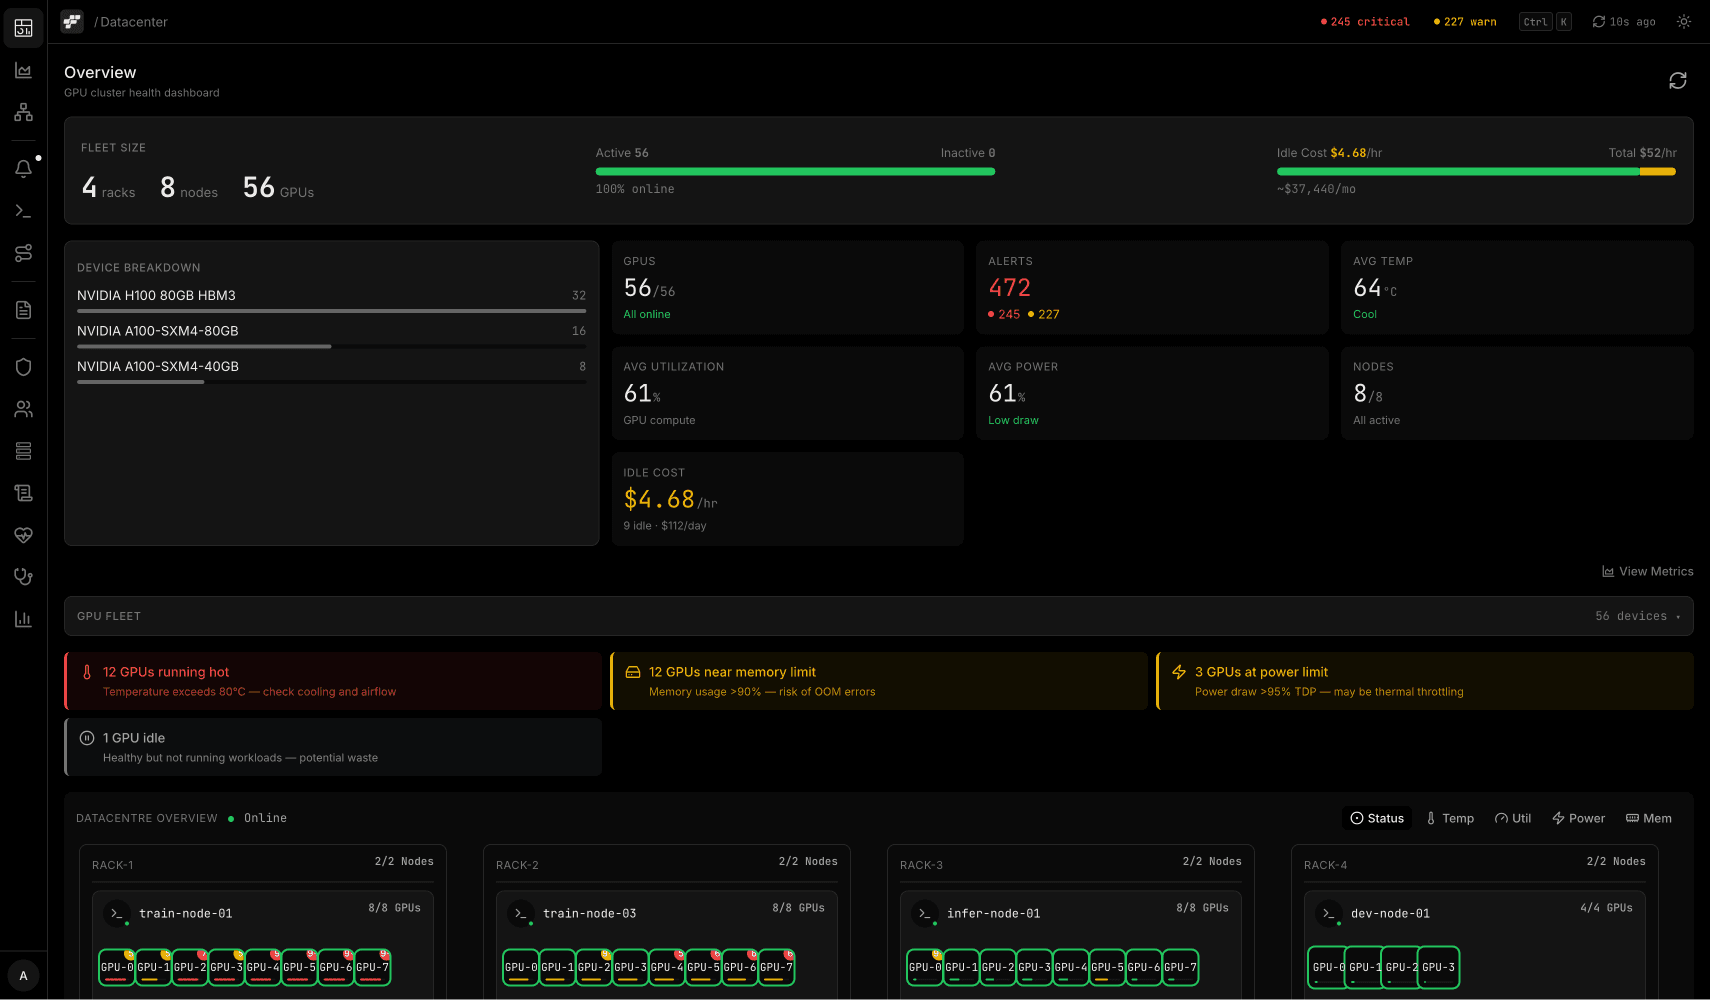
01 · Failures contained early
Faults caught and fixed before they cost a job.
02 · Measured against the design
Production checked against acceptance baselines.
03 · Engineers on the other end
Reliability engineers who know your cluster, on call.
- Read-only telemetry
- Outbound HTTPS only
- No inbound ports or SSH
- Non-root collector
Put reliability on contract.
Tell us about your fleet. We will tell you what it takes to keep it healthy around the clock.